TouchDesigner component
TD Fal
1,400+ fal.ai models in one TouchDesigner component.
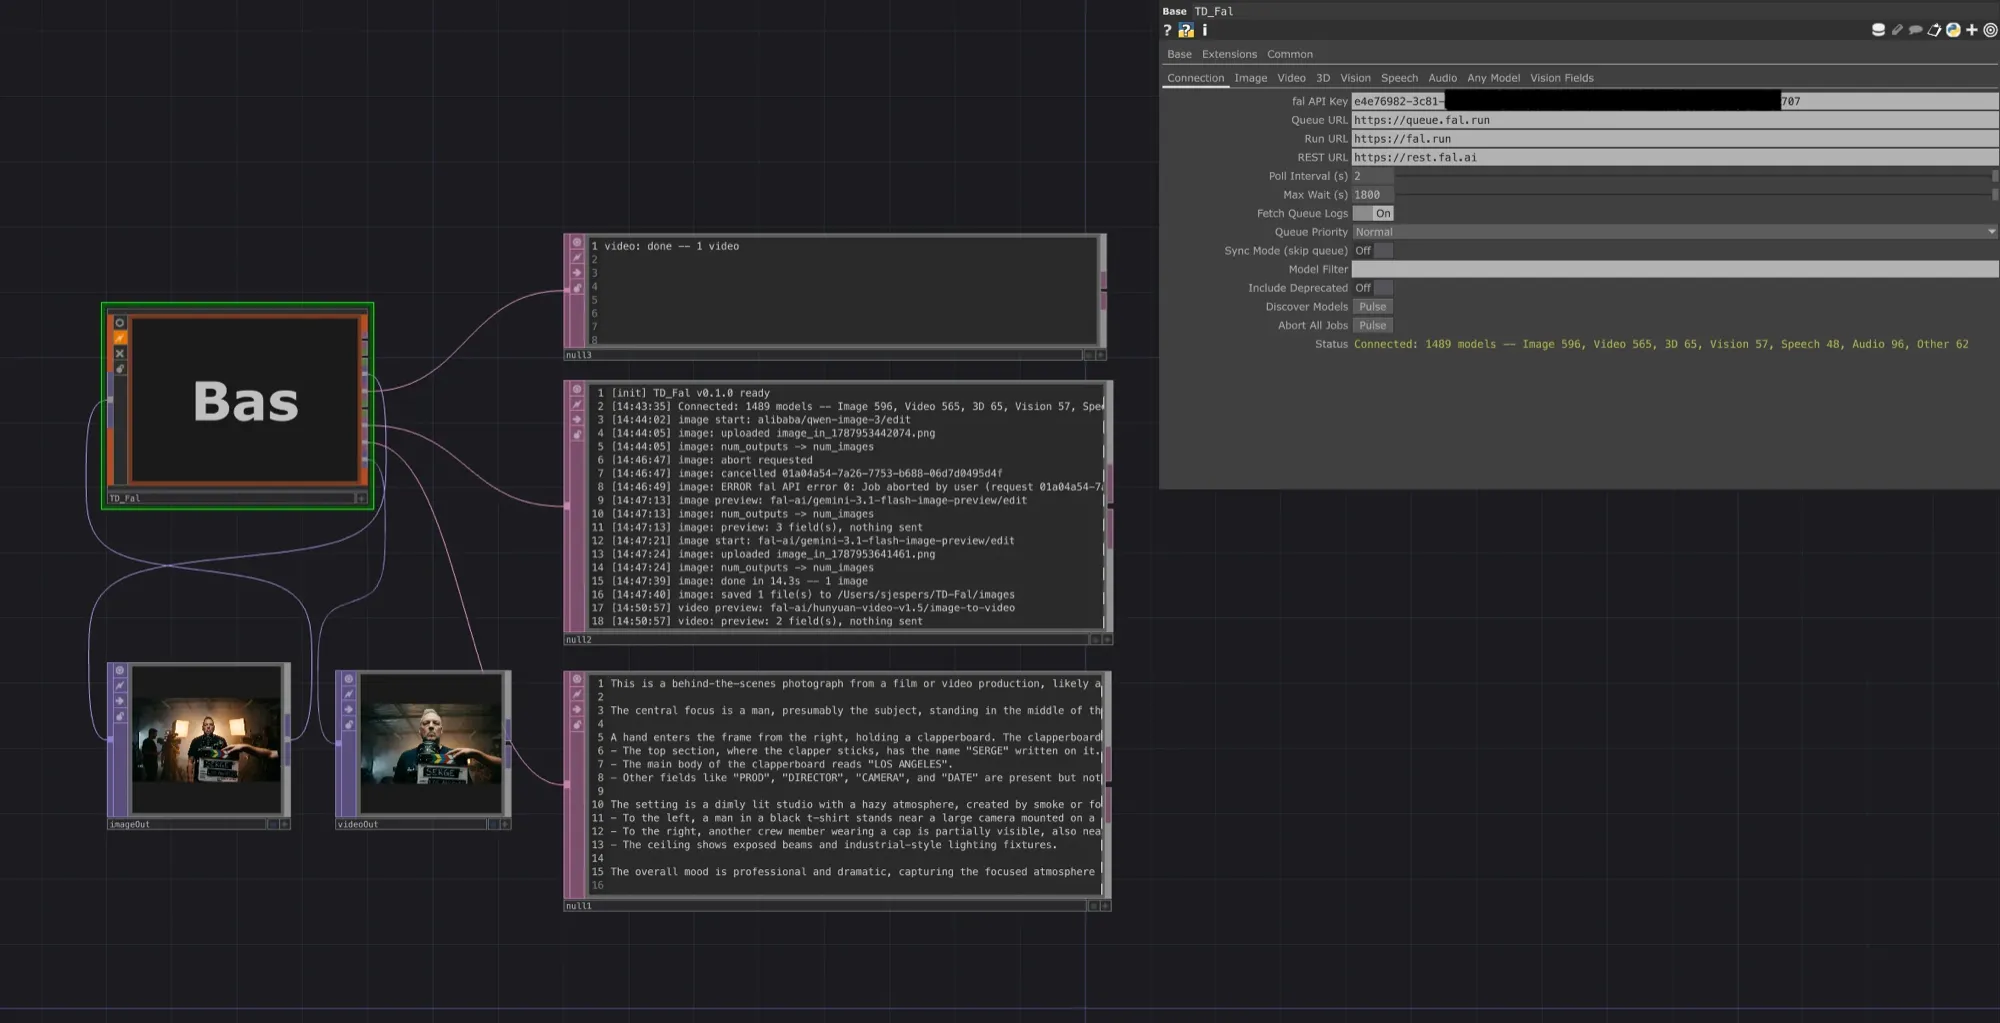
Load a schema, pick a model, hit Generate. TD Fal reads each model's input schema and builds real TouchDesigner parameters for it, so Gemini images, Kling video, Hunyuan3D, ElevenLabs voices and Flux all work from the same component.
- 1,400+
- fal.ai models
- 6
- modalities: image, video, 3D, vision, speech, audio
- 8
- parameter pages
- 0
- request bodies to write
Features
- 01
Schemas become parameters
Every fal endpoint declares its own inputs. TD Fal fetches the selected model's schema and generates real TD parameters for every field: enums as menus, numbers with their ranges, booleans as toggles.
- 02
Future-proof by design
Nothing is hard-coded per model, so models released after the component was written just work, and every field of every model is reachable.
- 03
Drive it like TouchDesigner
Because they're real parameters, they take expressions, exports and CHOPs like anything else in your network. Animate a seed. Map a knob to guidance.
- 04
Image, video, 3D, voice, audio
Outputs land as TOPs, CHOPs, glTF and DATs you can wire straight into your network. The Any Model page takes a bare endpoint id plus raw JSON for everything else.
- 05
Live model filter
Type flux, kling or elevenlabs and every dropdown refilters instantly from the cached index. No re-fetch.
- 06
Never stalls
Jobs run on background threads and report back through a queue drained on frame start. Poll interval, max wait, queue priority and abort-all are all on the Connection page.
Outputs
Drop it in. Wire it up.
Every output is a regular TouchDesigner operator, ready to wire into the rest of your network.
Why it's built differently
Most AI APIs share one request shape across all their models. fal doesn't: a Kling video model wants start_image_url and a string duration of "5", Hunyuan3D wants input_image_url, ElevenLabs wants text instead of prompt.
So TD Fal doesn't hard-code request bodies. When you generate, it:
- fetches the selected model's OpenAPI schema from fal,
- works out which of that model's fields play the role of prompt, reference image, seed, duration or voice,
- generates real TouchDesigner parameters for every other field the model declares,
- builds the request from all of the above, with your Extra JSON merged last.
Parameter pages
| Page | Models |
|---|---|
| Image | text-to-image and image-to-image (580) |
| Video | text, image, video and audio to video (530) |
| 3D | image-to-3D, text-to-3D, 3D-to-3D (53) |
| Vision | vision, image/video to text, LLM, JSON (56) |
| Speech | TTS, speech-to-text, speech-to-speech (48) |
| Audio | music, SFX, stems, audio-to-audio (95) |
| Any Model | any endpoint id plus raw JSON, including training and workflows |